Where Deepfake Detection for Content Moderation Fits in the Pipeline
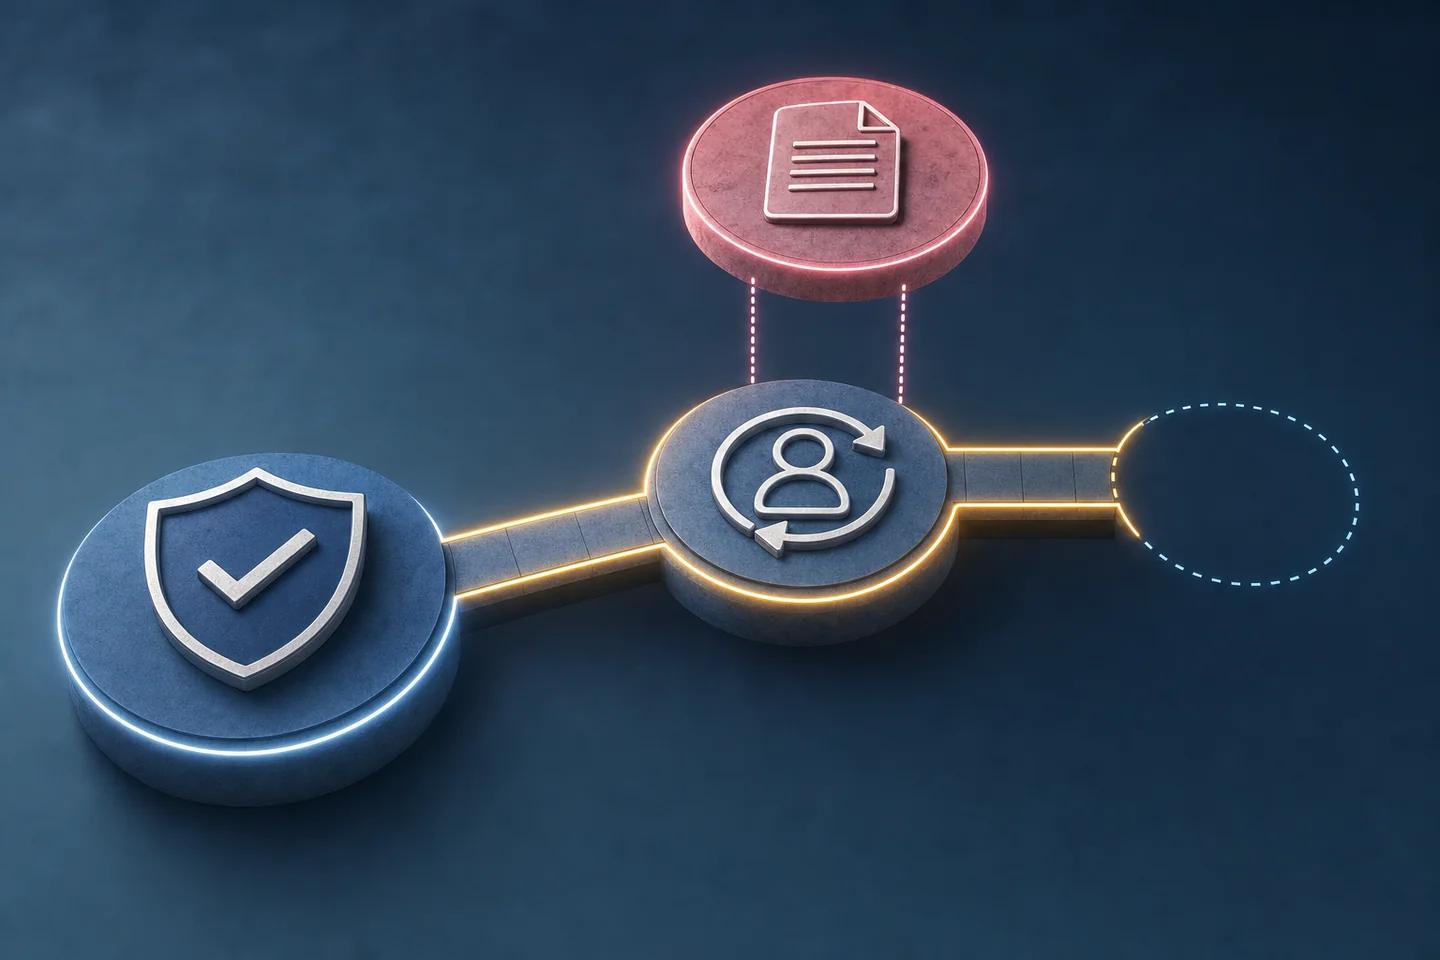
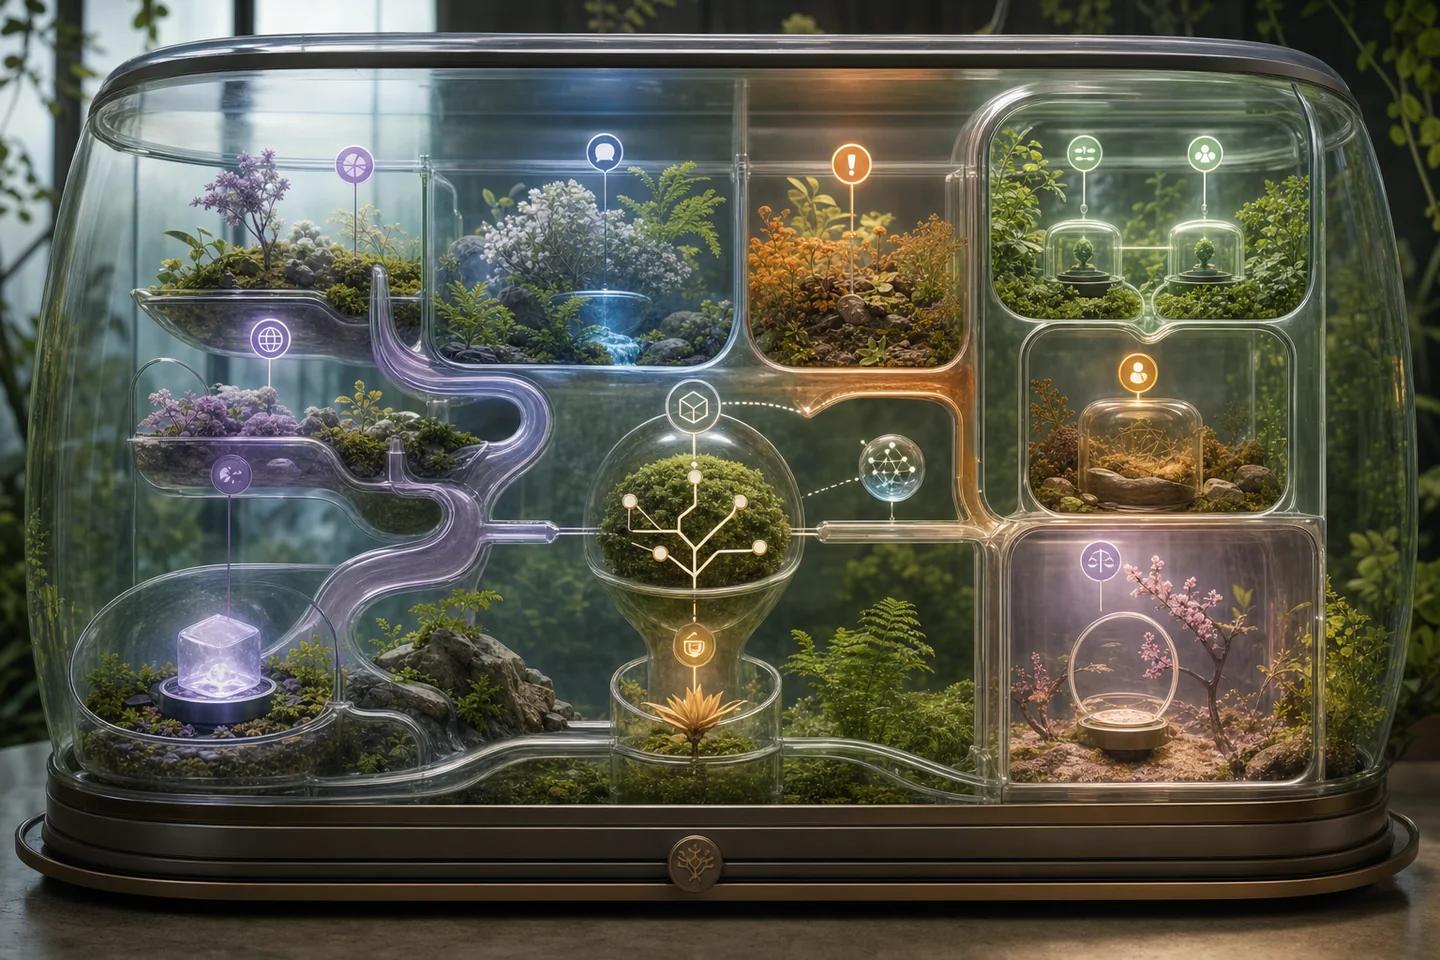
A moderation pipeline for synthetic media has four stages. Signals come first: provenance data such as C2PA Content Credentials or IPTC digital source type metadata, uploader self-disclosure, and classifier output on the media itself. Policy comes next, matching the content and its context against rules on deception, impersonation, intimate imagery, elections and harm. Action follows, from a label to reduced distribution to removal. Review and appeal sit around all of it, so that people can challenge wrong decisions.
Detection belongs in the signal stage. It is most useful where provenance is missing, which is most of the time, and where volume rules out human review of every upload. Its output should feed policy, never decide an outcome alone, because a great deal of synthetic media is harmless: satire, art, filters, dubbing and clearly labelled AI creations.
Rules That Shape Synthetic Media Moderation
In the EU, Article 50 of the AI Act applies from 2 August 2026. It sets transparency obligations for providers and deployers of certain AI systems, including generative systems and deepfakes, and the European Commission has published guidelines on those obligations alongside a Code of Practice on transparency of AI-generated content. Platforms that host such content need reliable ways to recognise and label it.
In the US, the TAKE IT DOWN Act, Public Law 119-12, criminalises publishing non-consensual intimate imagery, including digital forgeries, and requires covered platforms to remove reported content as soon as possible and no later than 48 hours after a valid request. In the UK, Ofcom's paper Deepfake Defences, published on 23 July 2024, analyses measures across the technology supply chain, from watermarking and detection classifiers to content filtering and media literacy, as part of its online safety work.
Why Crowd Flags and Fact-Check Notes Arrive Too Late
Many platforms rely on user reports, crowd-sourced context notes and partnerships with fact-checkers to catch deceptive media. These are valuable because people can judge context in ways classifiers cannot. They are also slow by design: a note or a report appears only after enough people have seen the content, and a viral fake can reach most of its audience in the first hours.
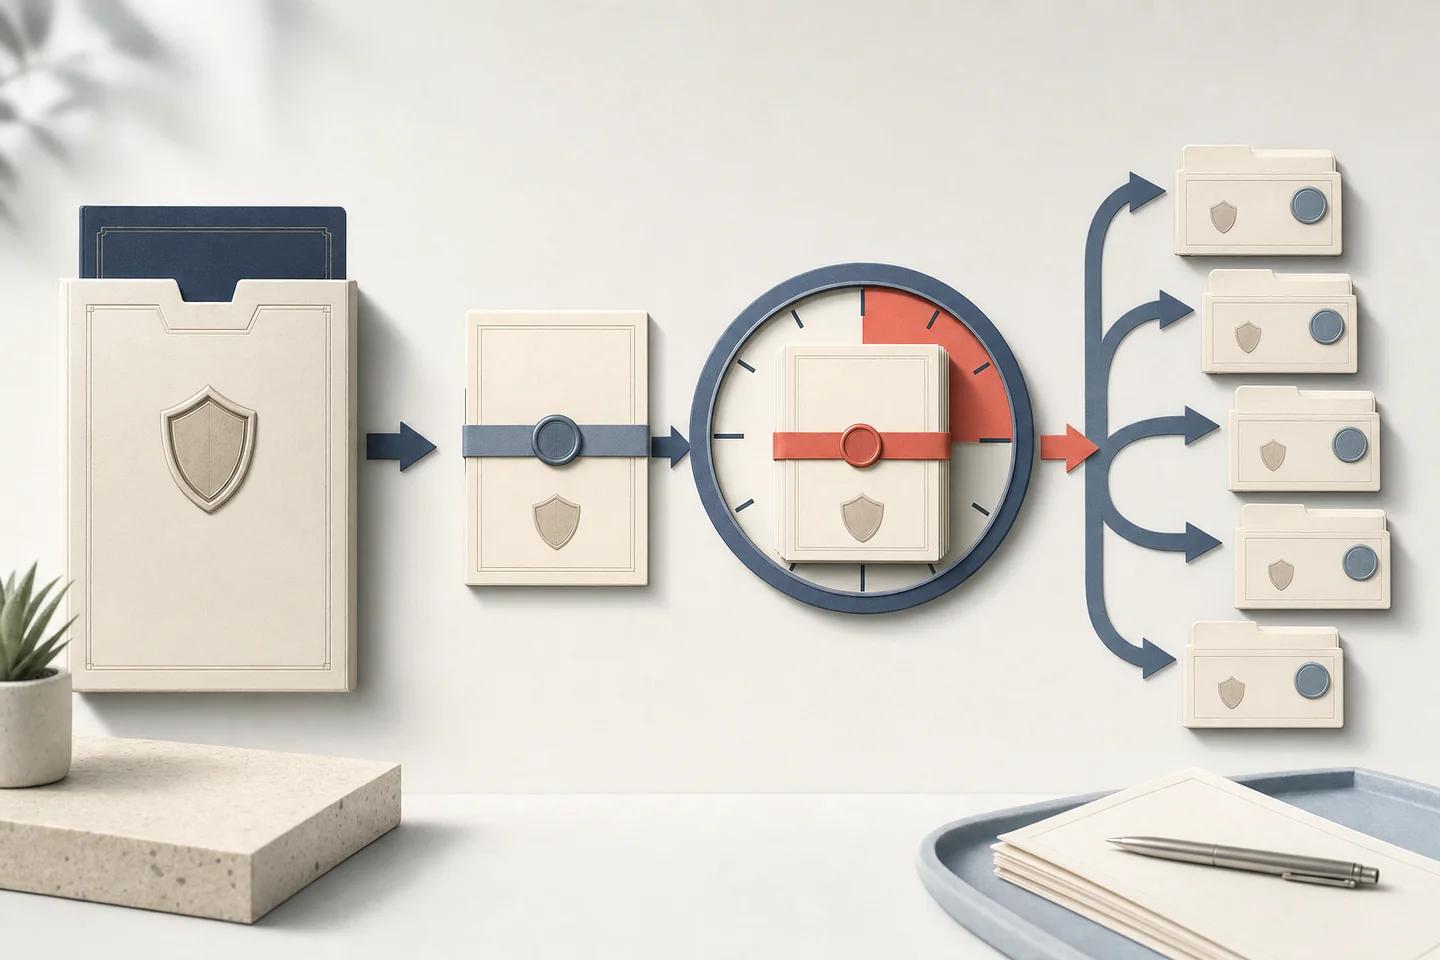
Upload-time screening moves the first decision earlier. A classifier that flags likely synthetic media at upload lets the platform apply a provisional label, hold distribution for high-risk categories such as content depicting real people in intimate or violent situations, or route the item to fast human review before it trends. Crowd context then adds to that decision rather than being the only defence.
What Platform Labelling Has Taught So Far
Labels based only on provenance indicators are easy to get wrong in both directions. Meta announced in 2024 that it would add AI info labels to a wider range of video, audio and image content when it detects industry standard AI image indicators or when people disclose AI use, keeping such content up with context rather than removing it, following feedback from its Oversight Board. It then renamed its earlier Made with AI label because photos with minor AI retouching were carrying the label, which did not match what people expected. For content only modified by AI tools, it moved the label into the post menu.
The lesson is that indicators say a tool was used, not how much or to what effect, and their absence says nothing at all. Content classifiers fill part of that gap by analysing the media itself. Platforms should combine both, and reserve prominent labels or restrictions for content where synthetic elements change what a viewer would believe about real people or events.
Matching Actions to Harm
A workable policy starts from harm and uses detection to decide how fast a case reaches it. The table shows a common pattern.
| Category | Main harm | Default action when detection flags it |
|---|---|---|
| Intimate imagery of a real person | Abuse, extortion, legal exposure | Hold distribution, priority human review, remove on confirmation; act on valid requests within 48 hours where the TAKE IT DOWN Act applies |
| Impersonation of a real person to deceive or defraud | Fraud, reputational damage | Limit distribution and review; remove if deception is confirmed |
| Election or crisis content depicting real events | Public deception at scale | Label and route to fast review with fact-check partners |
| Undisclosed AI content of fictional scenes | Low | Apply an AI label; no restriction |
| Satire, art and clearly labelled AI creations | Minimal | Allow; keep available for appeal and context |
Limits Trust and Safety Teams Should Plan For
Classifiers make mistakes at scale. Even a low false positive rate produces many wrongly flagged posts on a large platform, and errors may fall unevenly across languages, skin tones or content styles. NIST AI 100-4 (November 2024) notes that detection methods carry nonzero false positive and false negative rates and that a model built for one language may perform worse on others. Measure error rates by segment, keep humans on adverse decisions, and give users an appeal.
Detection also cannot judge context. A real video with a false caption, a satirical fake and a malicious fake can look the same to a classifier. Policy and human review exist for that reason.
How Neural Defend Supports Moderation Teams
For screening at upload, NeuroVerify takes a face image, video or audio in one API call and returns six signals, including Visual Safety Screening, Face Manipulation Detection, AI Generative Model Analysis, AI Pixel-Level Manipulation and AI Content Compliance, combined into a risk score with signal-level evidence. It returns results in under 200 ms at p95 on eligible image requests under defined test conditions. On the public VendorBench-100 benchmark of adversarial still images, Neural Defend ranked first of 36 systems with an MCC of 0.876 against 0.646 for the next-best vendor.
For escalations, appeals and legal requests, NeuroDetect gives reviewers a forensic workspace: the original file, explainability heatmaps and attention views down to regions, frames and audio segments, model and version context, an LLM-assisted summary linked to evidence, and an exportable report with observations, uncertainty and analyst notes. The platform's policy and its reviewers make every decision.
Evidence boundary
Limitations
- Classifier errors at platform scale can be large in absolute numbers and uneven across languages and content styles.
- Detection cannot judge context, intent or satire; policy and human review must.
- VendorBench-100 measures still-image detection only, not video, audio or moderation-scale throughput.
- Legal summaries here are for orientation only; obligations under the AI Act, TAKE IT DOWN Act and Online Safety Act depend on the service and jurisdiction.
Source record
Sources and references
- European CommissionGuidelines on Transparency Obligations for Providers and Deployers of Certain AI SystemsVerified October 19, 2026.
- U.S. CongressPublic Law 119-12, TAKE IT DOWN ActPublished May 19, 2025. Verified October 19, 2026.
- OfcomDeepfake Defences: Mitigating the Harms of Deceptive DeepfakesPublished July 23, 2024. Verified October 19, 2026.
- MetaOur Approach to Labeling AI-Generated Content and Manipulated MediaVerified October 19, 2026.
- National Institute of Standards and TechnologyNIST AI 100-4, Reducing Risks Posed by Synthetic ContentPublished November 20, 2024. Verified October 19, 2026.
- arXivVendorBench-100: A Unified Cross-Paradigm Benchmark for Deepfake Image Detection (v2)Published July 29, 2026. Verified October 19, 2026.