How Does Compression Affect Deepfake Detection?
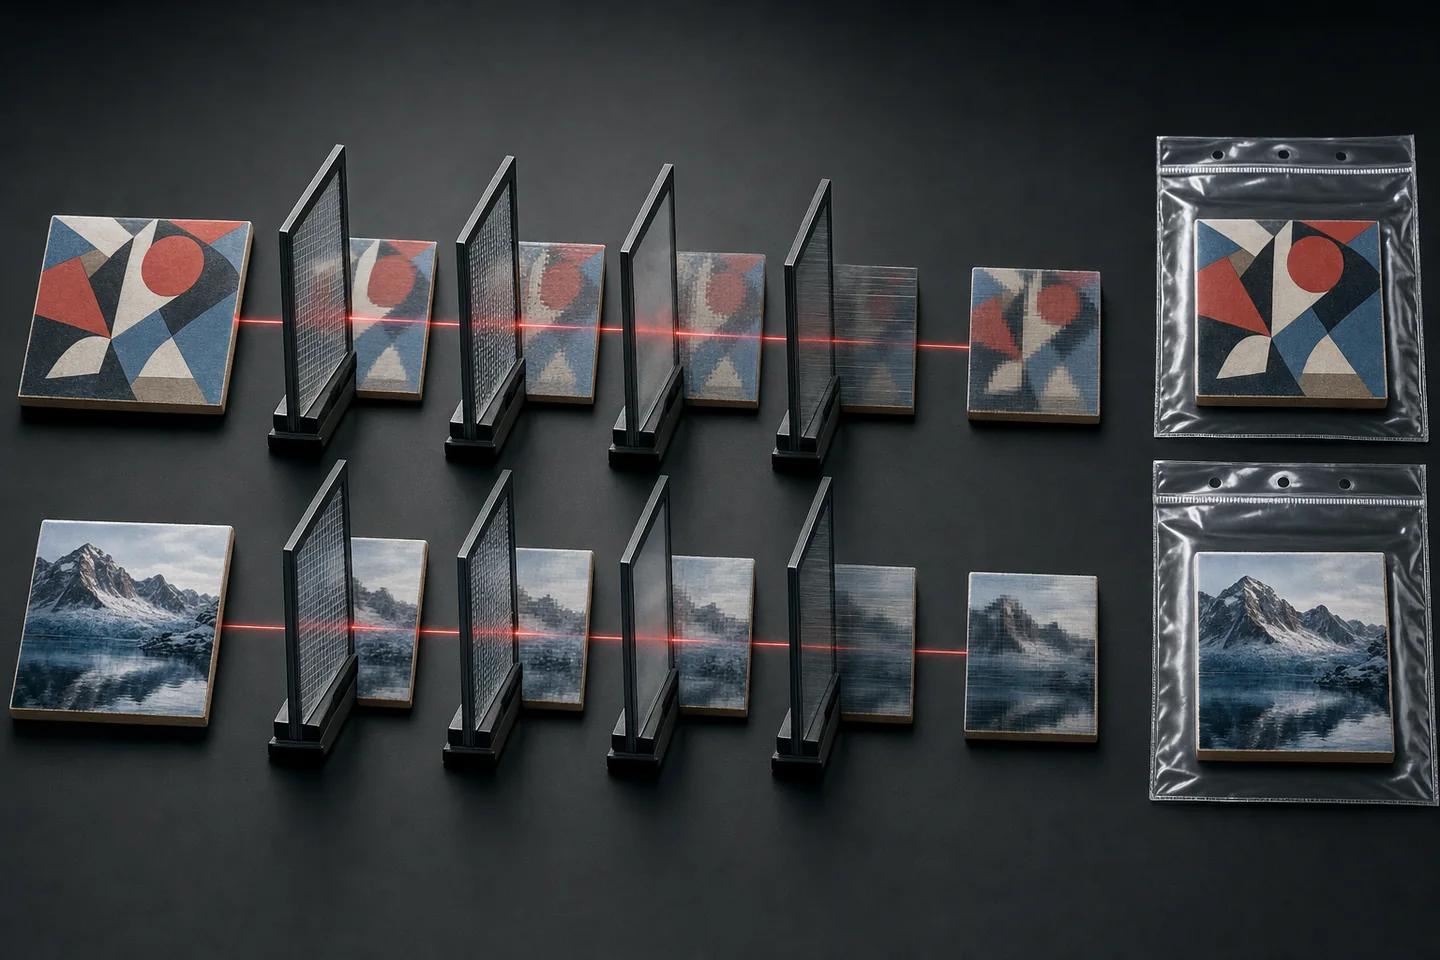
Compression affects deepfake detection by removing the evidence detectors look for and adding patterns of its own. Lossy codecs such as JPEG for images and H.264 for video divide a picture into blocks, keep the information people notice most, and discard fine high-frequency detail. Many manipulation traces live in exactly that detail: the blending seam around a swapped face, the regular texture left by a generator's upsampling layers, the noise pattern of a real camera sensor.
The same process adds new structure. Block edges, ringing around sharp lines and smeared colour are compression artefacts, and a detector that has not seen enough of them in training can mistake them for manipulation. Compression therefore pushes errors in both directions: real fakes slip through as their traces fade, and genuine but heavily compressed files can be flagged.
How Much Accuracy Do Detectors Lose to Compression?
The clearest measurements come from FaceForensics++, a benchmark published by Andreas Rössler and colleagues at ICCV 2019. They manipulated 1,000 real videos with four methods (DeepFakes, Face2Face, FaceSwap and NeuralTextures) and released each at three quality levels: raw, high quality using H.264 at a constant quantisation parameter of 23, which is visually nearly lossless, and low quality at a quantisation parameter of 40.
Every detector they tested lost accuracy as compression increased, and the older methods collapsed. The best model, XceptionNet, held up well at light compression but dropped 18 points at heavy compression. Steganalysis features with a support vector machine fell from 97.63% to 55.98%.
| Detector | Raw | Light compression (HQ, q23) | Heavy compression (LQ, q40) |
|---|---|---|---|
| XceptionNet | 99.26% | 95.73% | 81.00% |
| MesoNet | 95.23% | 83.10% | 70.47% |
| Bayar and Stamm | 98.74% | 82.97% | 66.84% |
| Steganalysis features + SVM | 97.63% | 70.97% | 55.98% |
| Human observers | 68.69% | 66.57% | 58.73% |
How Does WhatsApp or Social Media Compression Affect Deepfake Detection?
WhatsApp, Telegram, Instagram, TikTok, X and similar services resize and re-encode media on upload to save bandwidth and storage, unless the sender chooses a document or original-quality option where one exists. A clip forwarded through three group chats may have been decoded and re-compressed three times, losing detail at each step, and most platforms also strip metadata such as the capture device and time.
Screenshots and screen recordings are worse. They capture the file as displayed, at screen resolution, then compress it again, and they replace any remaining camera noise with the display's own rendering. By the time a viral clip reaches a fact-checker or a fraud team, it may carry little of the evidence present in the original.
This is the main reason Deepfake-Eval-2024 results are so much lower than laboratory benchmarks. The practical rule follows directly: ask for the original file from the earliest sender you can reach, request it as a document attachment rather than an inline photo or video, and record the chain of forwards you know about.
How Does Compression Change Deepfake Realism and Detection?
Compression makes deepfakes more convincing to people at the same time as it makes them harder for machines. Blur and blockiness hide the small errors viewers might notice, such as a flickering jawline or teeth that do not quite line up, and low-quality video has become normal enough on calls and social feeds that nobody expects sharpness. In the FaceForensics++ user study of 204 participants, human accuracy fell from 68.69% on raw video to 58.73% on low-quality video.
Attackers know this. Laundering a fake through compression or a screen recording is a cheap evasion step, and research shows deliberate perturbations can be designed to survive it: Hussain et al. reported at WACV 2021 that adversarial changes to deepfake videos remained effective after compression. A poor-quality clip of a high-stakes claim should raise suspicion, not lower it.
What Should Analysts and Teams Do About Compressed Media?
Teams should treat compression as part of the evidence and set rules for how much of it a decision can tolerate:
NIST's AI 100-4 report, published in November 2024, recommends that detector evaluations reflect benign distortions such as compression and resizing alongside adversarial changes. Ask any vendor for results on media degraded the way your own media arrives, not only on clean benchmark files.
- Get the earliest copy available, as a file rather than a screenshot or screen recording, and store it unchanged with a hash.
- Record what you know about the file's history: platform, forwards, conversions and any editing.
- Set a minimum resolution and bitrate for automatic decisions, and route anything below it to a recapture request or human review.
- In live channels such as video KYC, score the sharpest captured frames rather than the compressed stream alone.
- Read a clean score on a heavily compressed file as weak evidence, and combine it with source checks and context.
How Neural Defend Handles Compressed Media
Neural Defend's NeuroDetect is built for investigations where file history matters. Analysts upload an authorised image, audio, video or document into a case, and the analysis keeps model and version context. Detailed views show the original with explainability heatmaps and attention views down to regions, frames and audio segments, and the downloadable forensic report records observations, uncertainty and provenance, so a reviewer can state plainly when a result rests on a degraded copy.
For high-volume screening, NeuroVerify scores face images, video and audio in one API call across six signals and returns eligible image results in under 200 ms at p95. The public VendorBench-100 benchmark deliberately includes compressed research frames and opaque-provenance images among its 100 edge-case stills; Neural Defend ranked first of 36 systems there with an MCC of 0.876 against 0.646 for the next vendor. One VendorBench author also co-wrote the ARCAS 1B paper, and the benchmark covers still images only, so test on media compressed the way yours is.
Evidence boundary
Limitations
- The FaceForensics++ figures date from 2019 and cover face manipulation methods of that period; current detectors and generators behave differently, though the direction of the effect holds.
- Platform compression settings change over time and vary by upload option, so no fixed accuracy loss applies to a given app.
- VendorBench-100 includes compressed frames but covers 100 still images only, and one author also co-wrote the ARCAS 1B paper.
Source record
Sources and references
- arXivFaceForensics++: Learning to Detect Manipulated Facial Images (Rössler et al., ICCV 2019)Published January 25, 2019. Verified October 19, 2026.
- arXivDeepfake-Eval-2024: A Multi-Modal In-the-Wild Benchmark of Deepfakes Circulated in 2024Published March 4, 2025. Verified October 19, 2026.
- arXivAdversarial Deepfakes: Evaluating Vulnerability of Deepfake Detectors to Adversarial Examples (Hussain et al., WACV 2021)Published February 9, 2020. Verified October 19, 2026.
- National Institute of Standards and TechnologyNIST AI 100-4: Reducing Risks Posed by Synthetic ContentPublished November 20, 2024. Verified October 19, 2026.
- arXivVendorBench-100: A Unified Cross-Paradigm Benchmark for Deepfake Image Detection (v2)Published July 29, 2026. Verified October 19, 2026.